Every AI evangelist promises the same growth-stage playbook: deploy an autonomous network of agents, keep your headcount at zero, and watch your margins expand. It sounds perfect on a VC pitch deck.
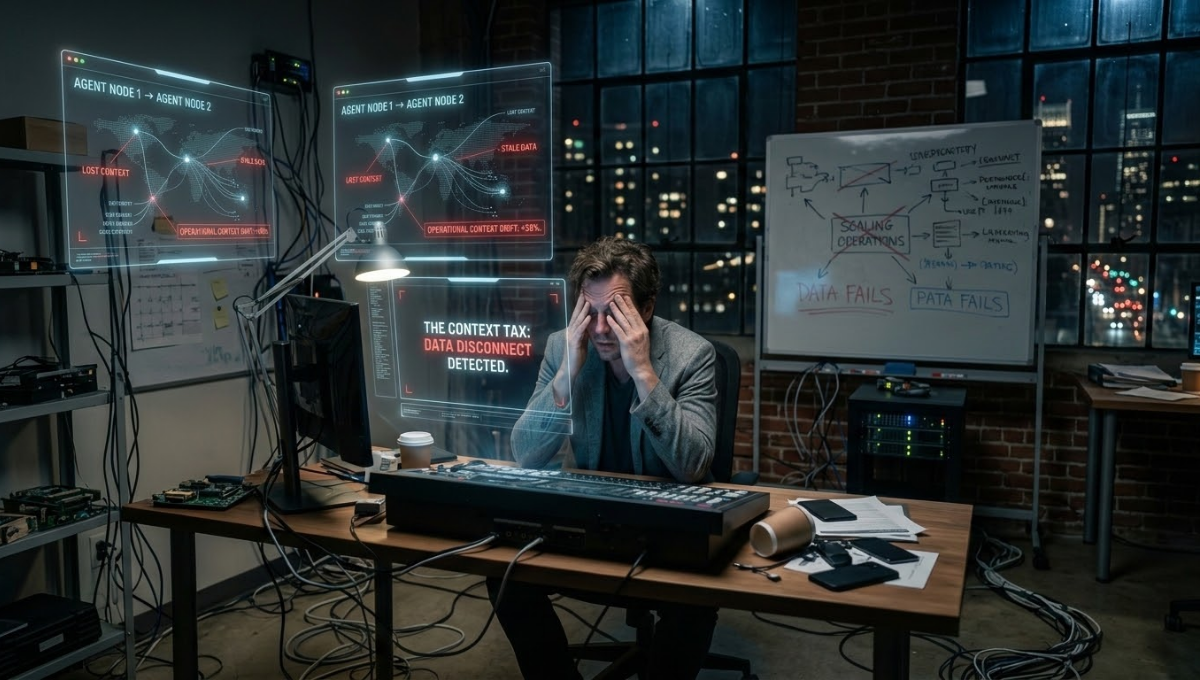
But when founders actually attempt scaling operations with AI, they hit a structural wall no one talks about: The Context Tax.
In a traditional startup, early employees aren’t just executing tasks; they act as the company’s connective tissue. They possess the tribal knowledge required to understand why an enterprise client is frustrated, how a specific product bug impacts sales pipeline velocity, and what the tone of a brand negotiation should be.
When you replace those human links with isolated AI agents, that institutional memory vanishes.
Why Standard AI Agent Architecture Drops the Ball
Most growth strategies treat AI adoption strictly as an automation problem. Founders connect a customer service agent to a product-logging agent via an API and assume the workflow is optimized for scaling.
It fails because standard AI agent architecture operates on localized data inputs, completely lacking systemic context.
For example, a customer support agent logs an engineering ticket based on a user prompt. However, it lacks the contextual awareness to know that this specific client represents 40% of the company’s ARR and has an upcoming contract renewal. The backend product agent receives the log, categorizes it as “low priority” based purely on technical severity, and buries it.
You haven’t built an efficient growth engine; you’ve built an automated pipeline for dropping critical enterprise data. The result isn’t a scalable business model—it’s just a faster way to alienate your market.
Moving From Simple Automation to Context Engineering
To successfully decouple headcount from revenue, a founder cannot just automate static tasks. You have to actively invest in context engineering by building a centralized context fabric.
This means your underlying AI infrastructure cannot just be a linear chain of command where Agent A passes a file to Agent B. Instead, you must build a continuous, real-time data graph that runs parallel to your operational agents. This system constantly updates and injects global company realities—such as account health, historical founder decisions, real-time runway metrics, and strategic priorities—into every single prompt execution across the entire network.
If your digital employee doesn’t have visibility into what your board of directors cares about this quarter, it cannot make autonomous tactical decisions for your business.
The New Founder Bottleneck: Managing Operational Context Drift
The fundamental shift for growth-stage founders isn’t moving from “firefighter to architect.” That is generic textbook fluff.
The real operational challenge is moving from managing human capital to auditing data fidelity. When you scale via an autonomous network, your primary systemic risk is no longer human drama or hiring delays; it is operational context drift. This is the phenomenon where your autonomous systems slowly drift away from your strategic intent because their underlying data inputs have gone stale.
The founders who build true, high-velocity SuperScalers aren’t the ones deploying the largest LLM models. They are the ones engineering the tightest data loops—ensuring that the machine knows exactly what the founder knows, at the exact millisecond it needs to execute.